Stalled feeds seen at once
Freshness tracked per source and per account.
Reliability & monitoring
The worst data failure is not the pipeline that stops. It is the one that keeps running while quietly reporting the wrong number. We instrument your pipelines so problems surface as an alert to your team rather than a question from your client.
What you get
Freshness tracked per source and per account.
Volume checks flag a day arriving 60% light before it's reported.
New columns, type changes and unexpected enums, on every source.
Warehouse figures compared with platform UIs within tolerance.
The problem
A hard crash is easy: something pages, someone fixes it. The costly failures are quiet. A platform adds an enum value and your CASE statement buckets it as null. A rate limit turns a partial response into a real-looking but incomplete day. A currency field changes type and spend numbers land off by a factor of a hundred. Each of these produces a dashboard that renders perfectly and is completely wrong, and you find out when a client does.
What we instrument
How we work
Map every existing pipeline and rank sources by how much reporting depends on them
Instrument freshness and volume first, since those catch the majority of real incidents
Add schema contracts and reconciliation for the highest-stakes sources
Tune thresholds against real history so the alerts stay credible, then hand over runbooks
What we use
Related work
We rebuilt the ETL, warehouse and automation layer across Amazon, Walmart, TikTok, Instacart and Criteo.
Read the case study
We built ETL pipelines into one data model and one dashboard for Amazon, Walmart and Instacart campaigns.
Read the case study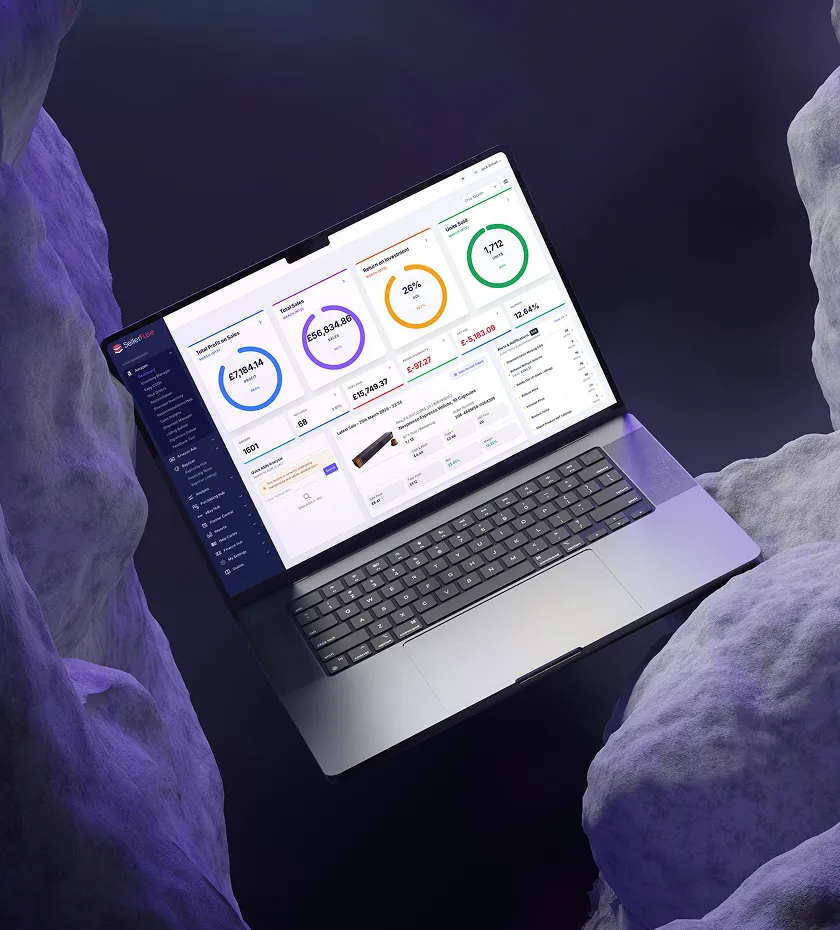
We built the SP-API and Ads API pipelines, live dashboards and automation behind SellerFuse.
Read the case studyFAQ
Yes, and it is a common first engagement. Observability sits alongside your existing pipelines rather than replacing them, so it does not require a rewrite. It also tends to be the fastest way to find out what is actually wrong before deciding what to rebuild.
Thresholds are set from your real historical variance rather than round numbers, seasonality is accounted for, and alerts carry severity so a late non-critical source does not page anyone at 3am. An alert channel people mute is worse than no alerting, so we tune it against replayed history before going live.
Schema drift is an upstream source changing shape without warning: a renamed field, a new type, an added enum value. Ad platforms ship these changes continuously. Because the pipeline keeps running, the damage is silent and can span weeks of reporting before anyone notices.
Yes. Some clients take the tooling and runbooks and run it themselves; others keep us on for on-call coverage and fixes. Both are available, and the tooling is identical either way, so you are never locked in.
Go deeper
Guide
Scaling an Amazon agency from dozens to thousands of clients breaks manual reporting completely. Here's the infrastructure that makes that scale possible.
Read the guideGuide
Amazon sellers juggle data across SP-API, the Ads API, and spreadsheets. Here's how a proper ETL pipeline unifies it into one reliable source of truth.
Read the guideRelated
Incremental, orchestrated, tested pipelines that re-run without a babysitter.
Learn morePacing projected to month end and anomaly alerts routed to the account owner.
Learn moreA written assessment of your data stack and a prioritized roadmap, in 2 to 3 weeks.
Learn moreWe will review your current pipelines and report where a silent failure could reach a client dashboard today.