Tested models
Assumptions asserted, so silent wrongness fails the run.
dbt & Airflow
dbt and Airflow are the two tools that turn a collection of scripts into a data platform. We implement both with the parts teams usually skip: tests, CI, documentation, and DAGs that fail safely instead of silently.
What you get
Assumptions asserted, so silent wrongness fails the run.
Idempotent tasks, sensible retries and alerts that reach a person.
dbt build on every pull request, so broken models never ship.
Docs, lineage and working sessions at handover.
The problem
Installing dbt does not make a project maintainable. We regularly review dbt repos with one flat directory of 200 models, no tests, and business logic copy-pasted across a dozen files. Airflow tends to arrive with the same pathology: DAGs with hard-coded dates, tasks that are not idempotent so a retry corrupts data, and no alerting, so failures are noticed when someone opens the UI. The tools are correct; the practices around them are what break.
What we implement
How we work
Review the current project or scripts and identify what is fragile versus merely untidy
Restructure the transformation layer with tests, refactoring duplicated logic into shared models
Rebuild orchestration with idempotent tasks and alerting that reaches a person
Add CI, then train the team on the workflow so it holds after we leave
What we use
Related work
We rebuilt the ETL, warehouse and automation layer across Amazon, Walmart, TikTok, Instacart and Criteo.
Read the case study
We built ETL pipelines into one data model and one dashboard for Amazon, Walmart and Instacart campaigns.
Read the case study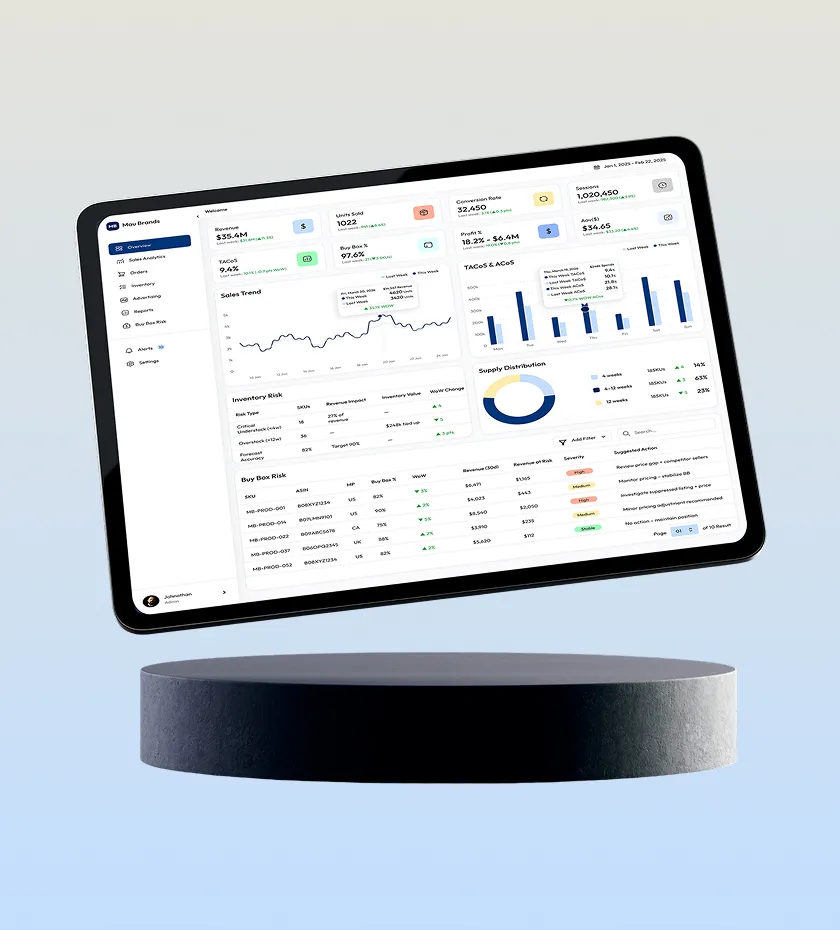
We built Mau Brands' Amazon analytics platform: sales, inventory, ads and pricing in one view.
Read the case studyFAQ
Airflow has the larger ecosystem, more managed options and a much bigger hiring pool, which is why we default to it. Dagster has a genuinely better developer experience and treats data assets as first-class, which suits teams with strong engineering practices starting fresh. Either is defensible; the deciding factor is usually who maintains it.
Almost always, and it is usually worth doing. dbt gives you version control, testing, documentation and lineage, none of which stored procedures offer. The migration is mostly mechanical, and the real gain is that transformation logic becomes reviewable in pull requests instead of living undocumented in the database.
Every model should assert that its primary key is unique and not null, and every relationship it depends on should be tested. Beyond that, test the assumptions that would cause a wrong number rather than a failed run, since those are the ones that reach clients. Perfect coverage is not the goal; catching silent wrongness is.
Both, and the training matters more. A dbt project nobody on your team can extend has just moved the bottleneck to us, which is not a good outcome for you. Handover includes the repo, the CI, the docs and working sessions with your analysts.
Go deeper
Guide
A practical guide to building a marketing data warehouse with dbt and Snowflake: architecture, modeling layers, metric definitions, and the mistakes that sink these projects.
Read the guideGuide
Amazon sellers juggle data across SP-API, the Ads API, and spreadsheets. Here's how a proper ETL pipeline unifies it into one reliable source of truth.
Read the guideRelated
Incremental, orchestrated, tested pipelines that re-run without a babysitter.
Learn moreFreshness, volume and schema drift alerts, plus reconciliation to platform figures.
Learn moreMulti-tenant access, dbt modeling and a predictable credit bill.
Learn morePoint us at the repo or describe how transformations run today, and we will report what is fragile and what to fix first.